Teaching Foundation Models the Laws of Physics
March 16, 2026
Authors
 Vlad Medvedev
Teaching Foundation Models the Laws of Physics
Based on: Physics-Informed Fine-Tuning of Foundation Models for Partial Differential Equations, Medvedev et al., ICLR 2026 · Fraunhofer IISB, Erlangen
Scientists and engineers constantly need to simulate physical systems — how heat spreads through a material, how sound waves travel through a room, how air flows around a wing. The traditional approach is to run a numerical solver: a program that crunches through the underlying equations step by step. It works well, but it's slow and expensive. For problems that need thousands of simulations (think: optimizing a design, or running a real-time control system), the cost becomes prohibitive.
Machine learning has emerged as a fast alternative. Instead of solving equations from scratch, you train a neural network on many pre-computed examples. The network learns the patterns and can then predict new results in milliseconds. The catch is that these models are brittle — they work well for situations similar to their training data, but fail when something genuinely new comes along.
Foundation models for PDEs
Most physical phenomena — heat flow, wave propagation, fluid dynamics — are described mathematically by partial differential equations, or PDEs. The latest generation of AI models for physics takes inspiration from large language models. Just as ChatGPT is pre-trained on a huge variety of text and can then be adapted ("fine-tuned") to specific tasks, researchers have built PDE foundation models pre-trained on a large variety of physical simulations. One prominent example is POSEIDON, developed at ETH Zurich, which is pre-trained on diverse fluid dynamics problems. The hope is that this broad prior knowledge helps transfer to new, unseen physics problems.
Fine-tuning still requires labeled data — pairs of inputs and correct outputs — which means running the expensive numerical solver for at least some examples in the new domain. Recent work such as the POSEIDON paper shows that achieving the best performance often requires increasingly large amounts of labeled simulation data. In our paper at ICLR 2026 Workshop on AI & PDE, we ask: can we do better? What if, instead of showing the model tons of correct answers, we simply tell it which physical laws it must obey?
Physics as a teacher
This is the key idea behind physics-informed machine learning. Physical equations like the Poisson equation (governing heat conduction, electrostatics, and more) express an exact mathematical relationship between inputs and outputs. If a model's prediction violates that relationship, you can measure the violation — called the residual — and use it as a feedback for training, without ever needing a ground-truth solution.
Our work introduces a framework that applies this idea to fine-tuning the POSEIDON foundation model. Rather than only minimizing the difference between predicted and known solutions, the model also minimizes how much its predictions violate the governing equations.
Figure 1 — The framework
The model takes a physical input (e.g., a source), produces a predicted solution, and is trained by minimizing both the mismatch with known solutions (data loss) and the degree to which the prediction violates the governing equation (physics loss). The two can be combined in a hybrid approach.
Three training strategies are compared throughout the paper:
- Data-driven — standard fine-tuning using labeled paired input/output examples.
- Physics-informed — no labeled solutions at all; only the equation residual guides training.
- Hybrid — a small amount of labeled data plus unlabeled examples augmented on the fly during training to enforce the physics-informed loss.
Additionally, we investigate whether it is better to fine-tune a pre-trained foundation model — POSEIDON in our experiments — or train a neural operator from scratch.
Downstream task #1: Poisson equation
Results: less data, more physics
The benchmark task is the 2D Poisson equation — a type of PDE that POSEIDON was not trained on during pre-training. This ensures the model must genuinely adapt to new physics rather than recall something familiar.
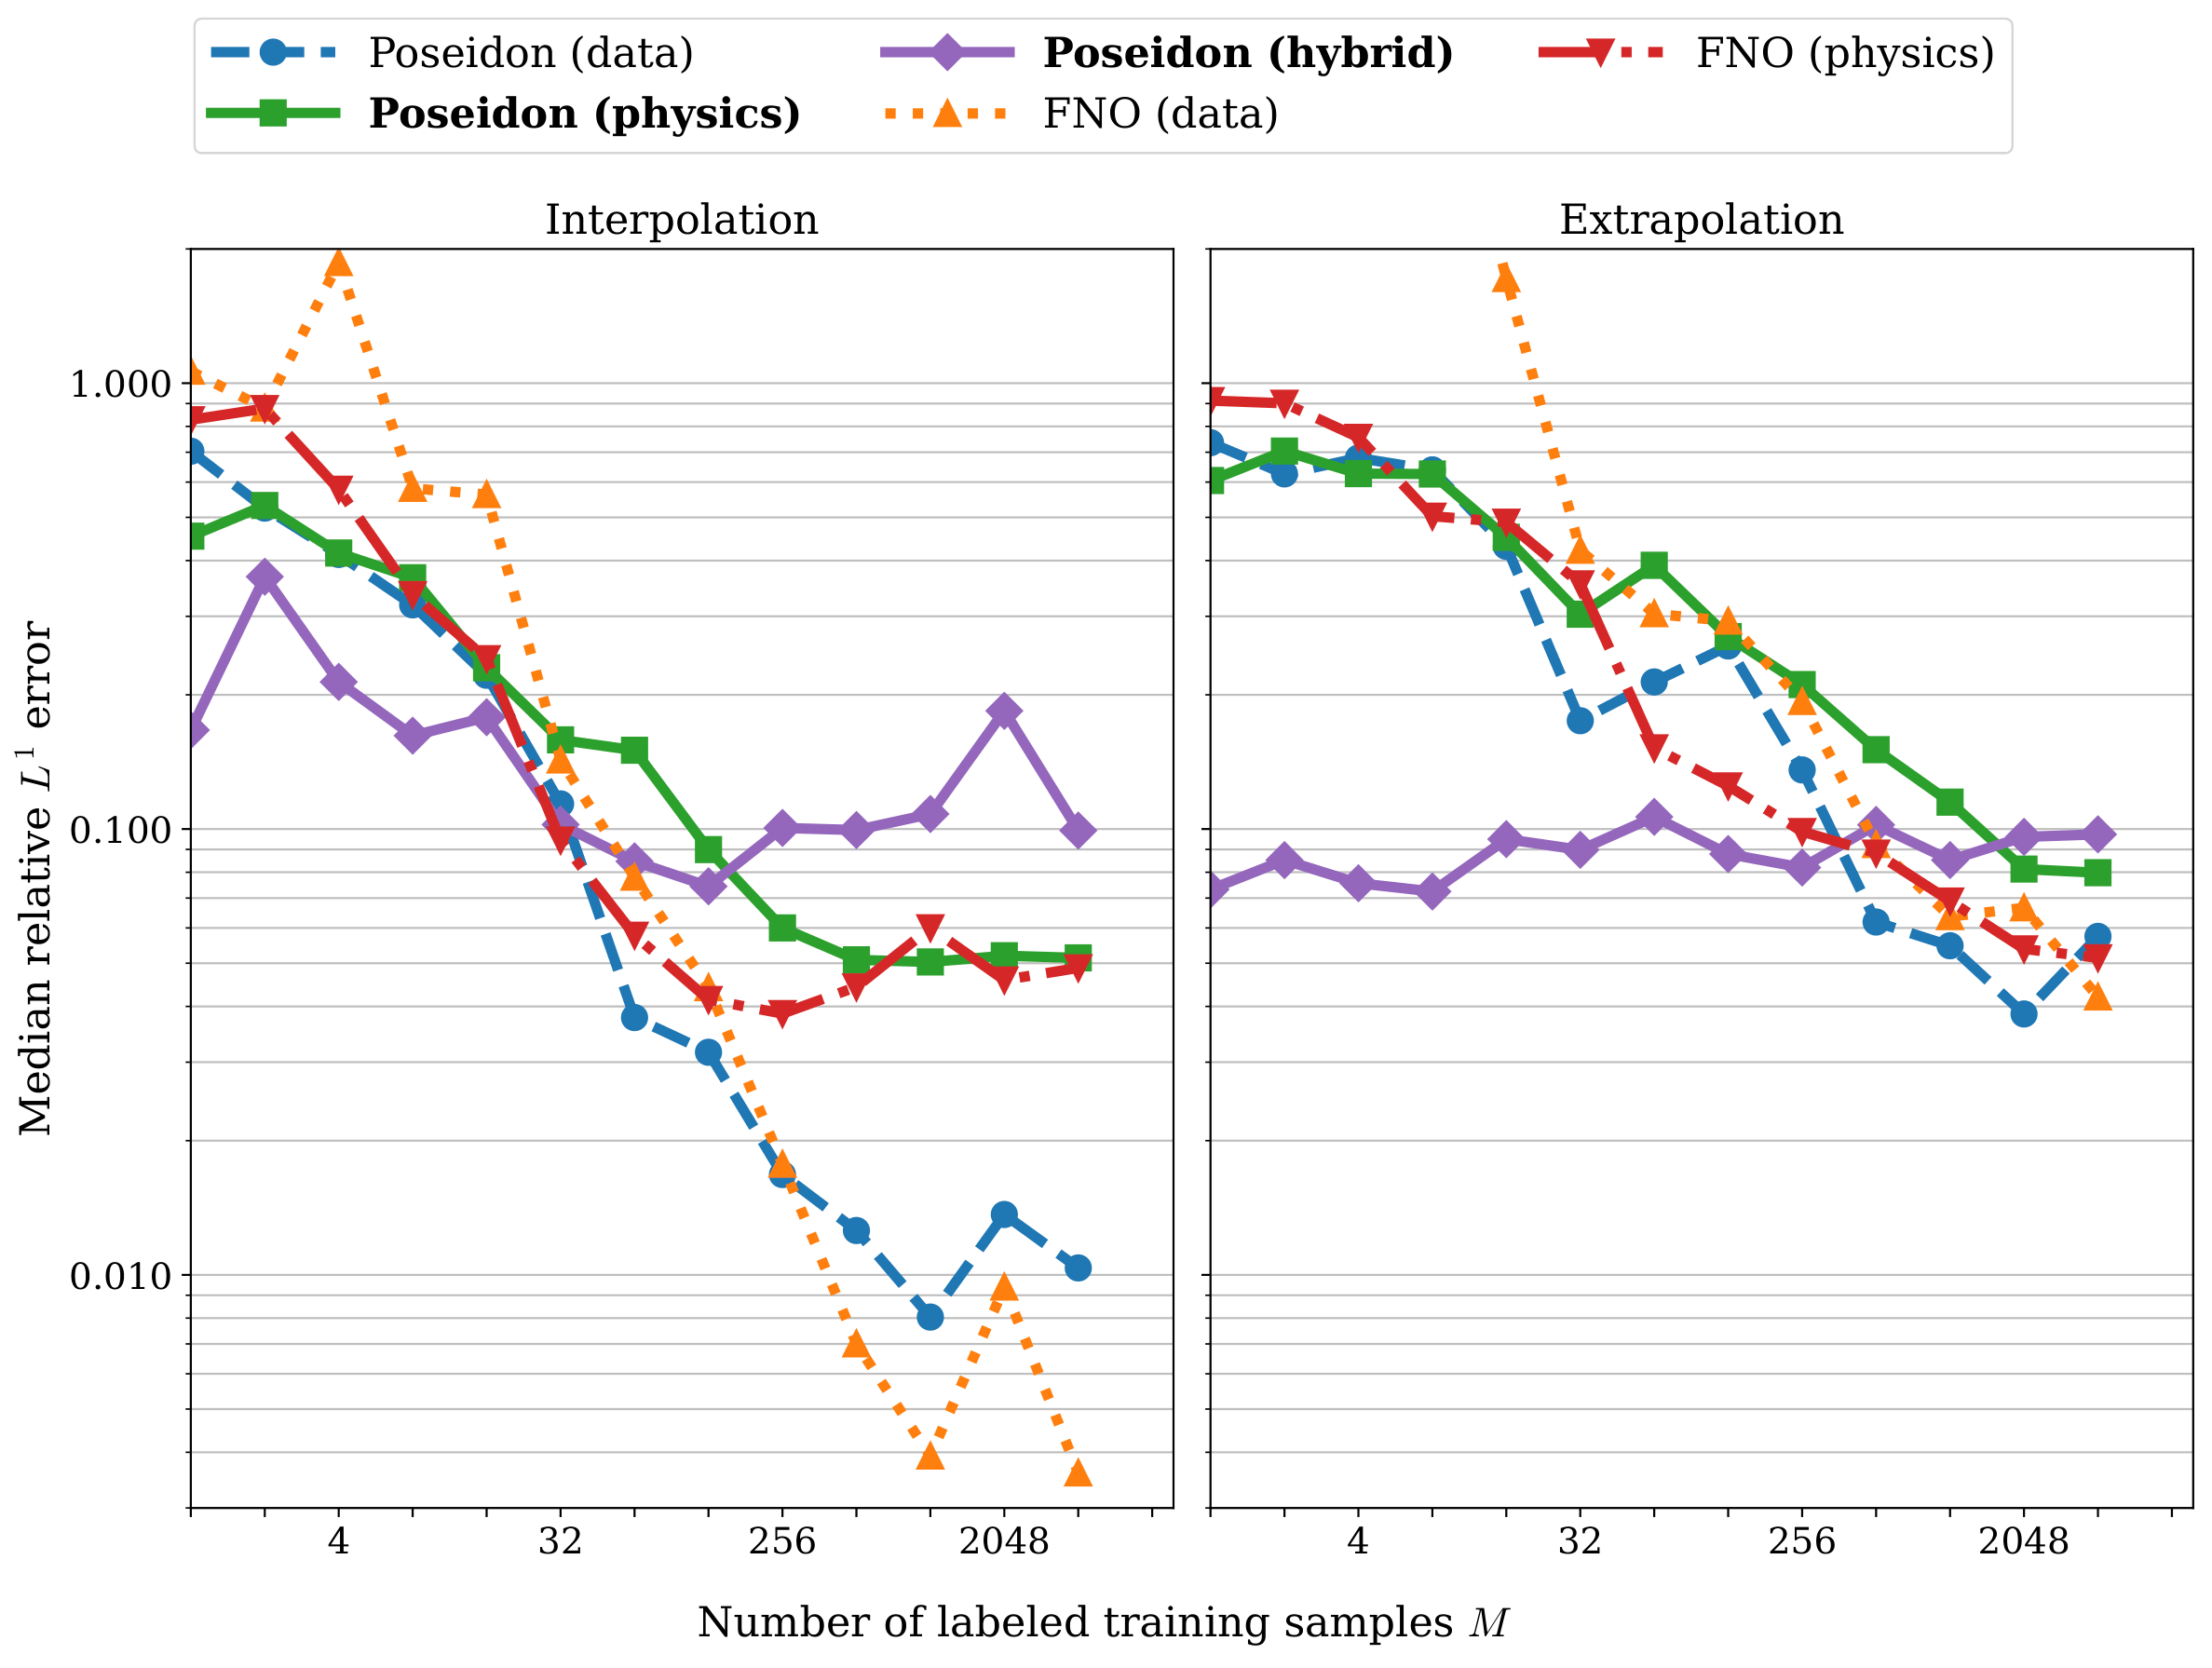
Figure 2 — Error vs. number of labeled training samples
Two panels show "interpolation" performance (test inputs similar to training inputs) and "extrapolation" performance (completely different input shapes). The hybrid model achieves the lowest error with very little data, and can produce useful results from a single labeled example.
In the low-data regime, the results are striking. The hybrid POSEIDON model can learn to solve the Poisson equation reasonably well from just a single labeled example. The purely data-driven model needs at least 32 examples to reach the same level. The physics-only model — with zero labeled solutions — is also competitive with the data-driven baseline when data is scarce.
With abundant data, the data-driven model eventually wins on raw prediction accuracy. But there's a catch: while its pixel-wise errors are low, checking whether its predictions actually satisfy the underlying equation tells a different story. The data-driven model has learned a sophisticated pattern-matcher — it doesn't truly "know" the physics.
Does it generalize to unseen inputs?
The extrapolation experiment is more demanding. Models are trained on smooth, blob-shaped source patterns and then tested on qualitatively different shapes: sinusoidal waves, spirals, checkerboards, random polygons. This is a test of whether the model has learned something genuinely physical, or just memorized patterns.
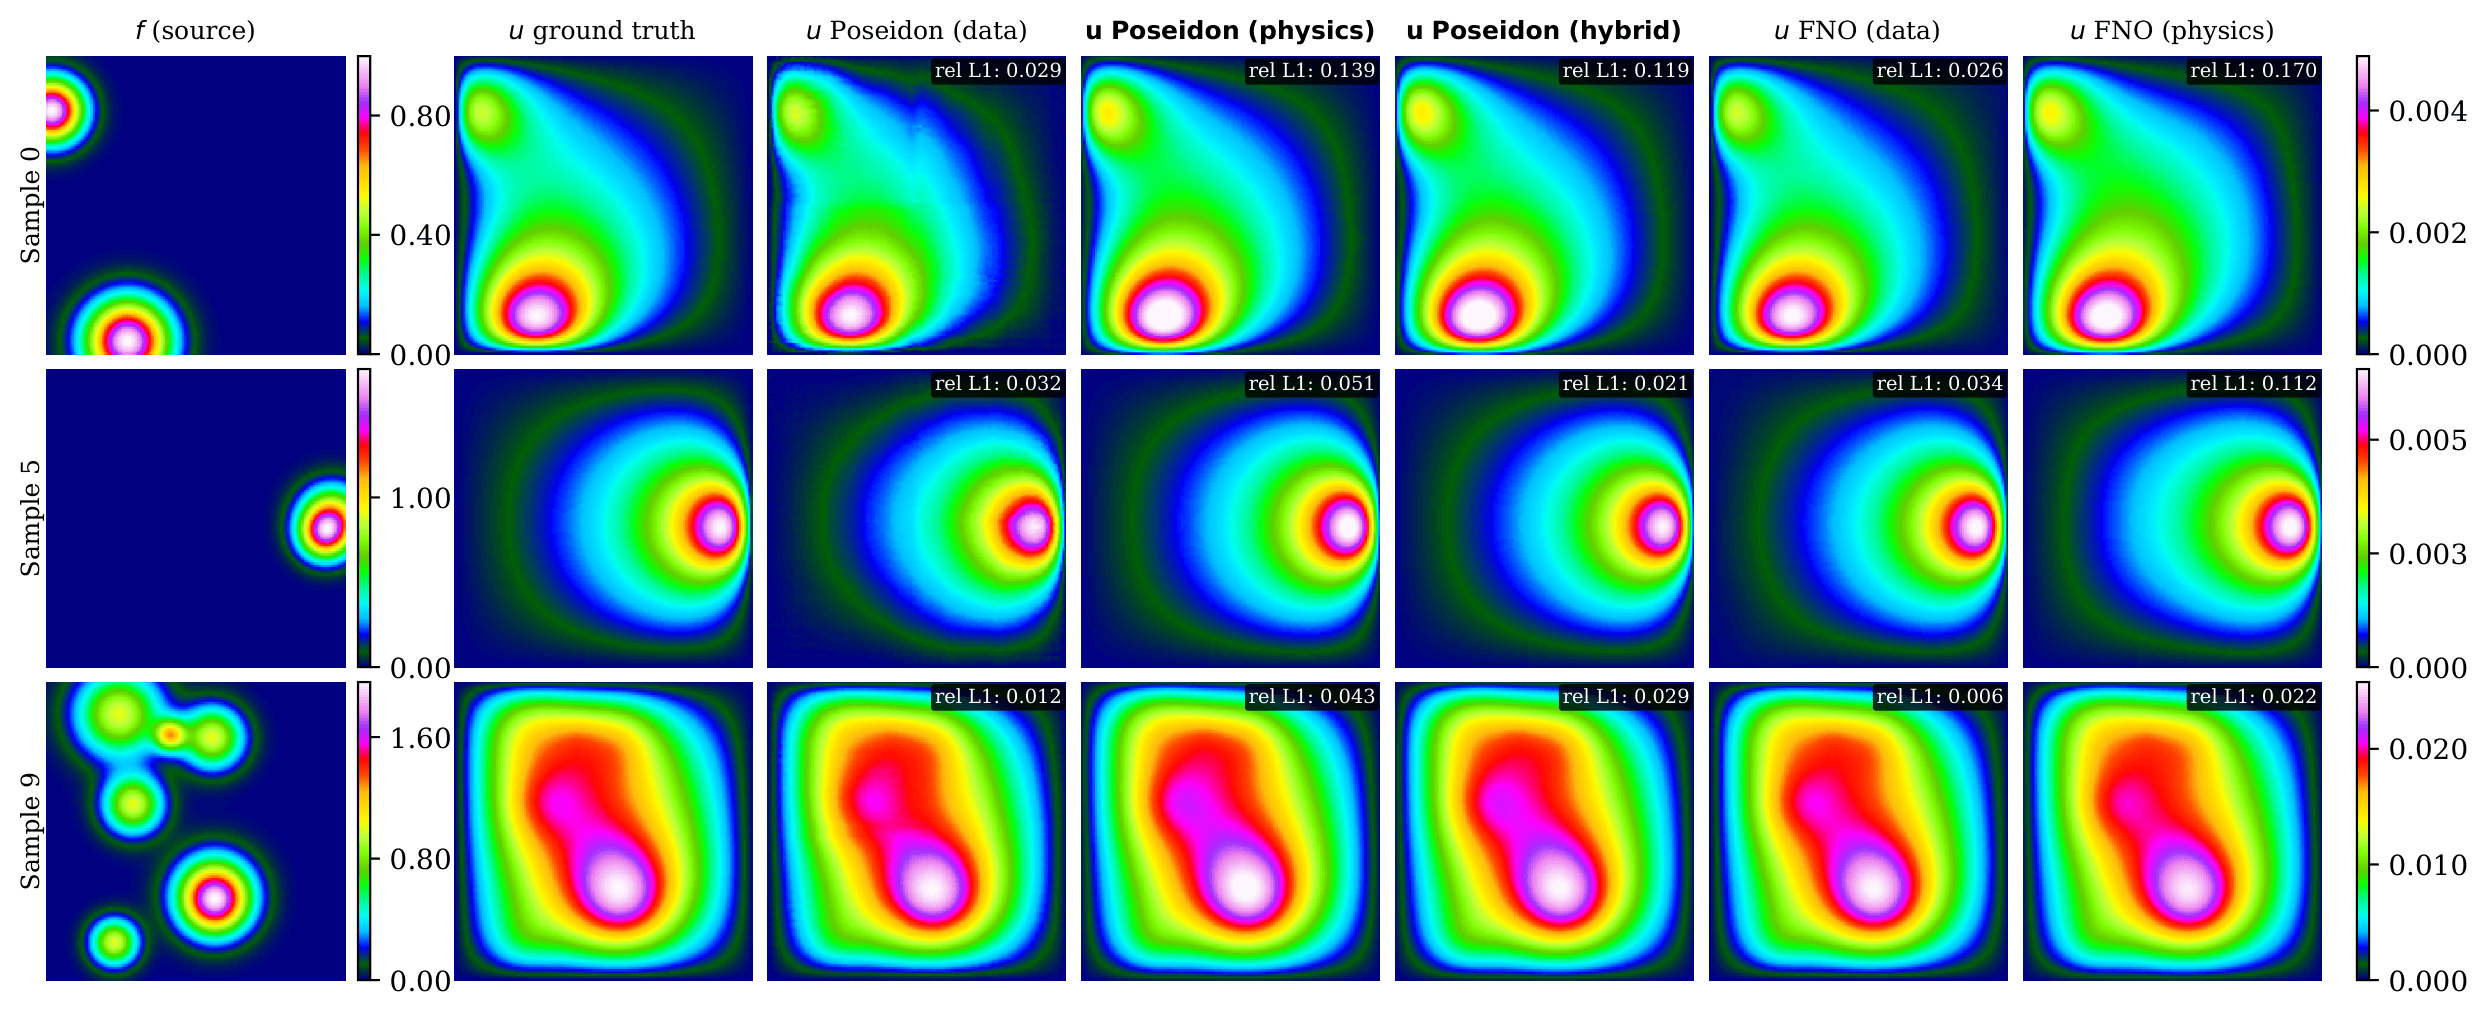
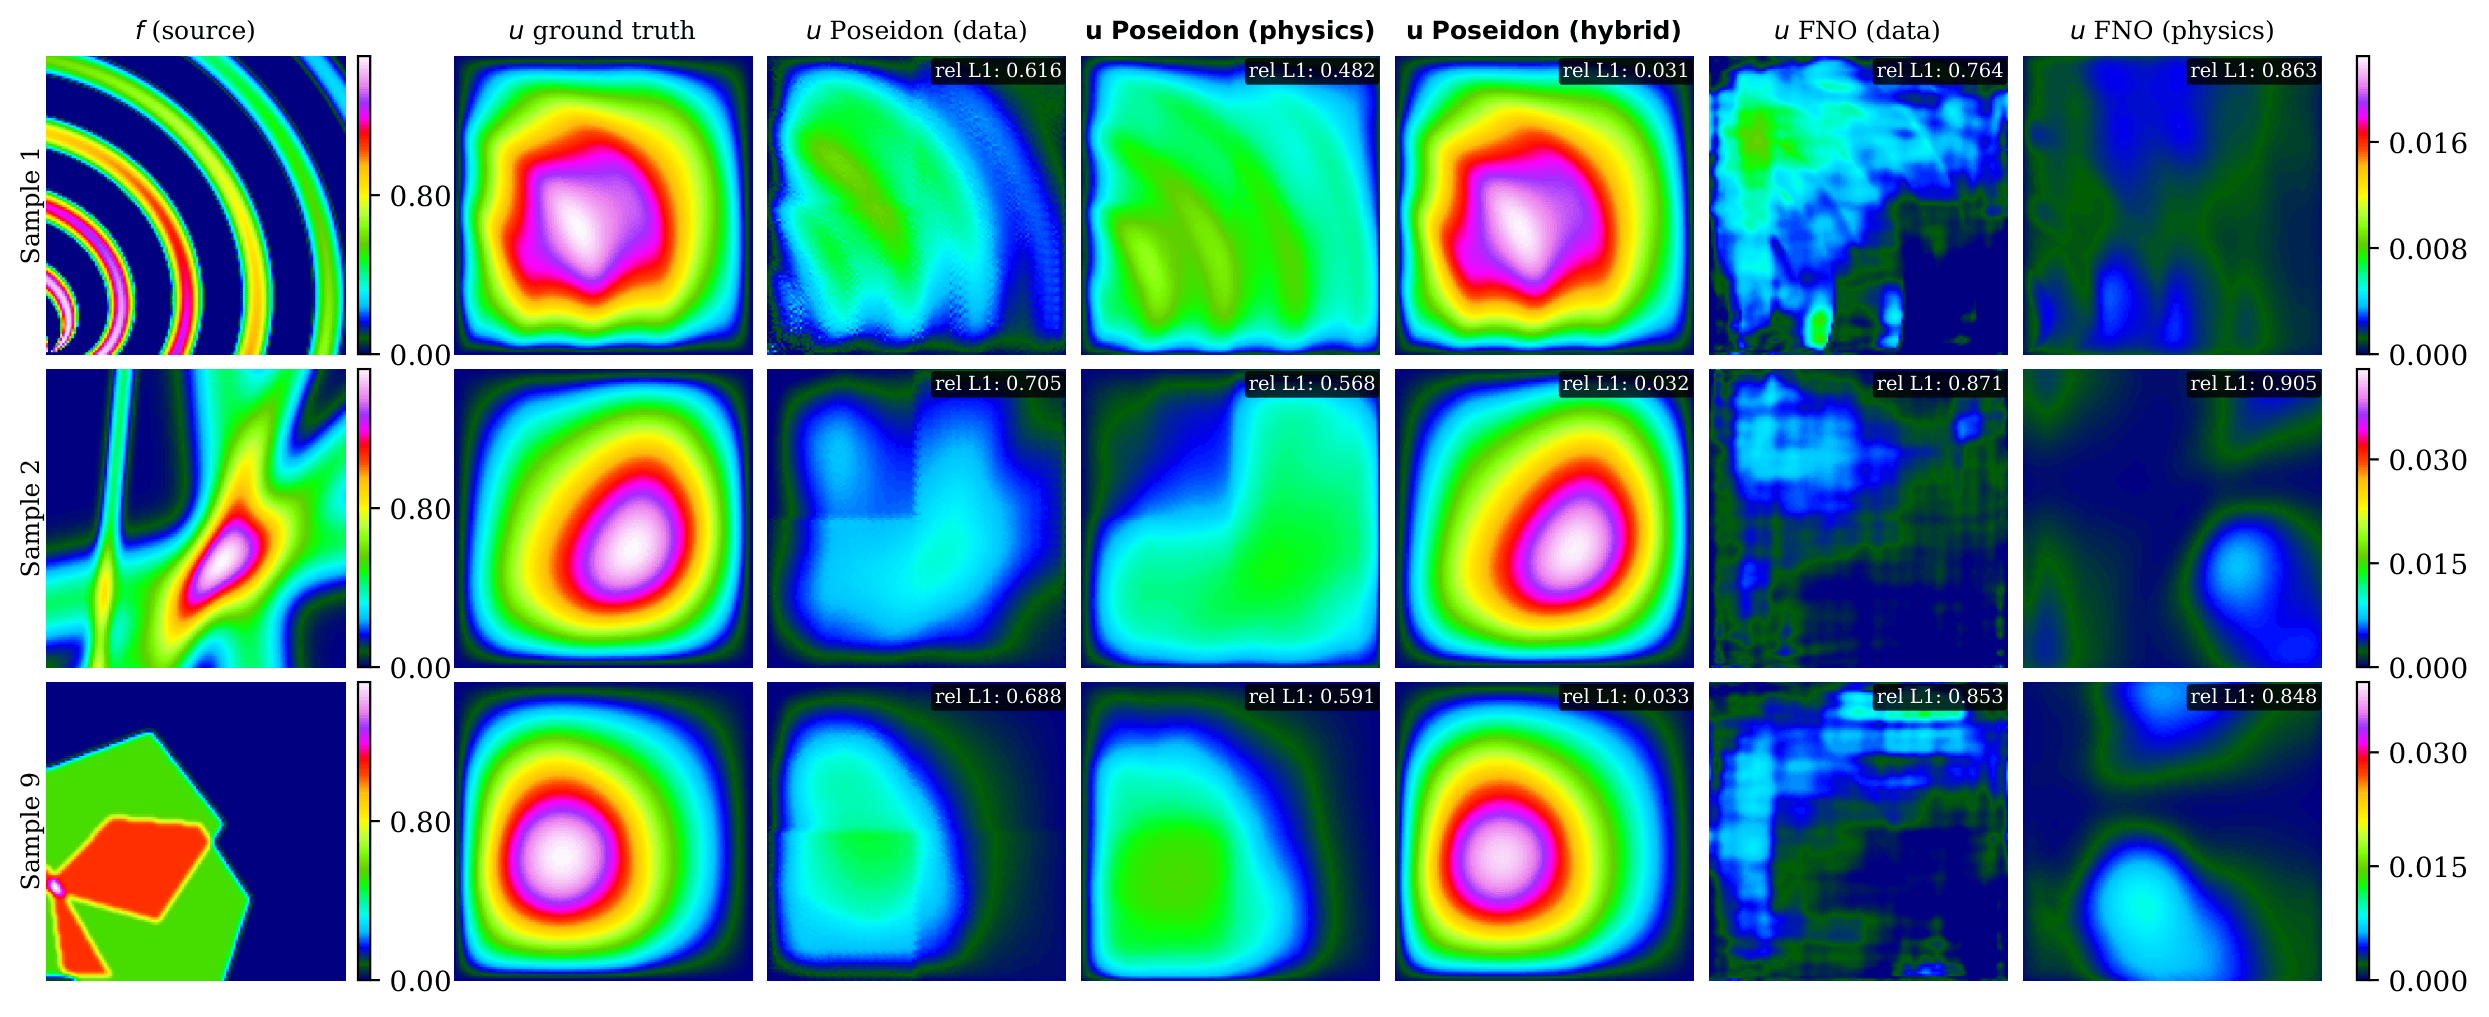
Figure 3 — Poisson equation: interpolation (upper rows) and extrapolation (bottom rows)
For interpolation task, all models were trained on 2048 labeled examples — most predictions are reasonable. In the extrapolation regime, the models were trained on a single example and tested on completely unseen source shapes.
When trained on only one example and confronted with completely unseen source shapes, all models except the hybrid fail. The physics-informed approach acts as guardrails: even without knowing what the correct output looks like, the model is constrained to produce something physically plausible.
Downstream task #2: Helmholtz equation
To check that the results are not specific to the Poisson equation, the paper also evaluates the approach on the Helmholtz equation, which models wave propagation at a fixed frequency. The setup is similar: train on Gaussian-shaped coefficient fields, test on wavy-stripe patterns.
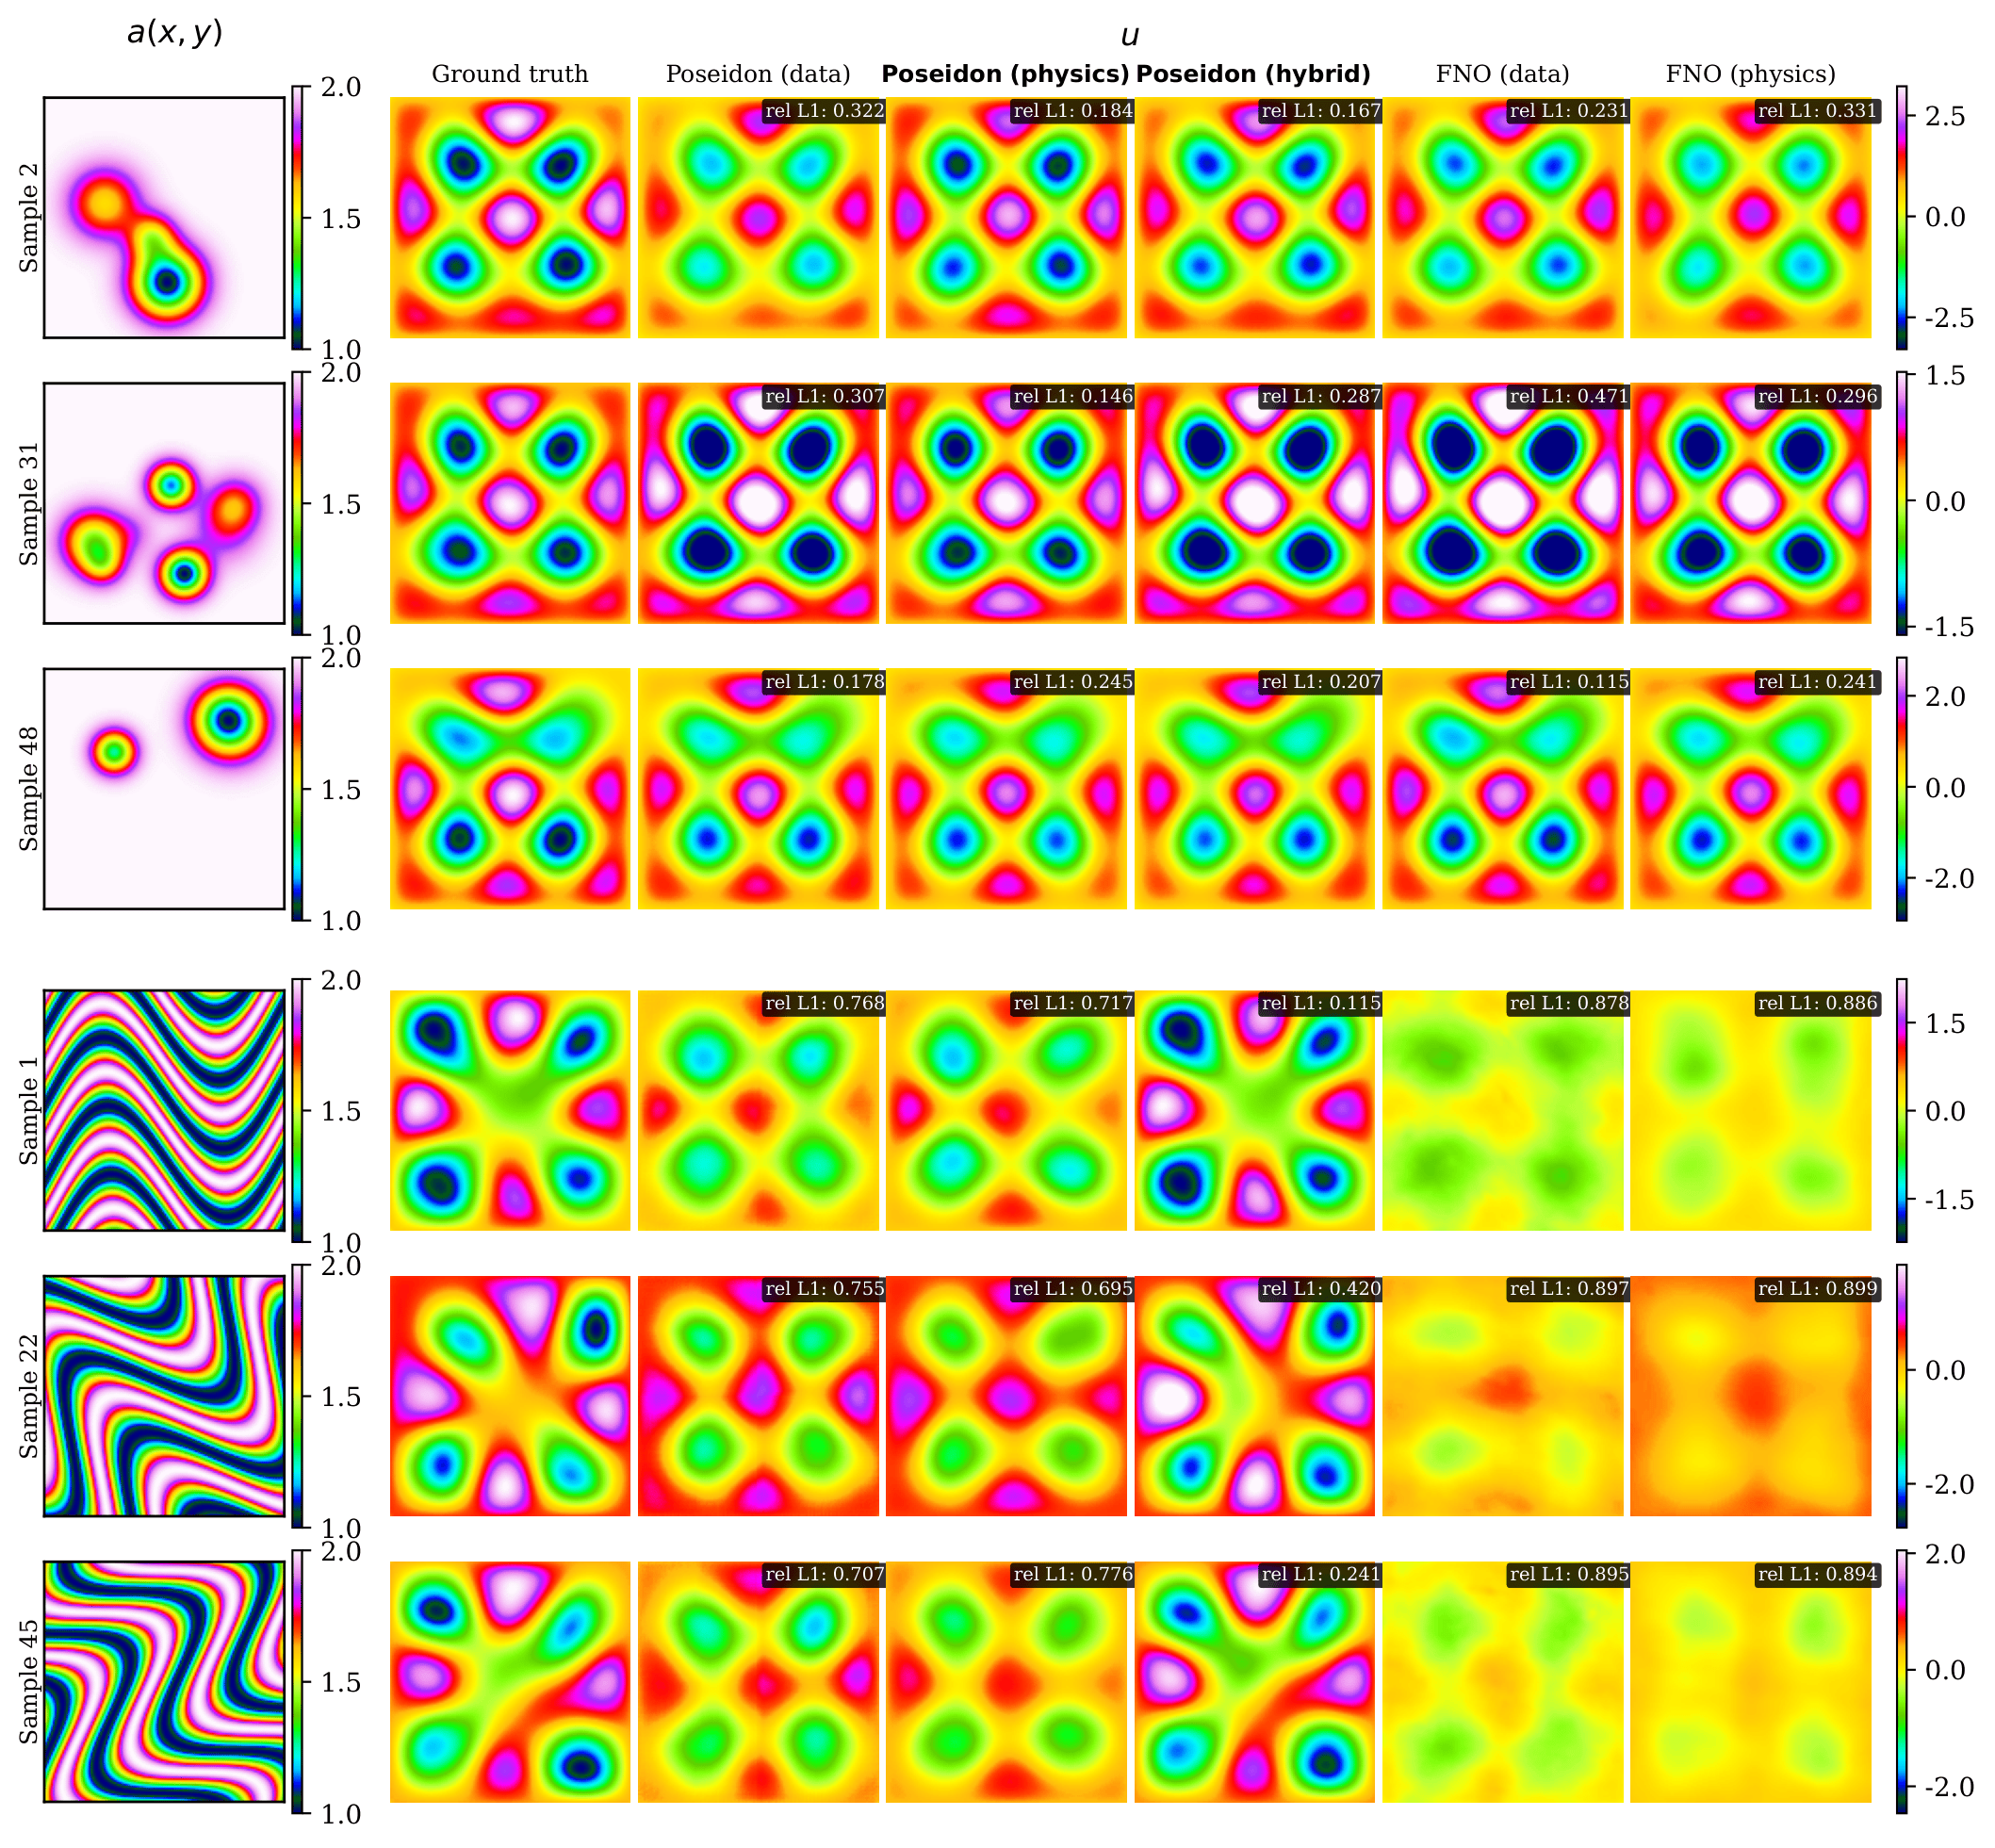
Figure 4 — Helmholtz equation: interpolation (upper rows) and extrapolation (bottom rows)
Qualitative comparison of model predictions trained on 2048 samples constructed as a superposition of a random number of Gaussian components. Out-of-distribution test cases include unseen sources constructed from rotated wavy stripes. The physics-informed model again generalizes robustly to qualitatively different inputs.
The Helmholtz results broadly confirm the Poisson findings. Physics-informed fine-tuning provides better extrapolation and physical consistency, even for the more oscillatory solutions that wave equations produce.
What this means
The core contribution of this paper is demonstrating, for the first time, that physics-informed fine-tuning works for large pre-trained PDE foundation models — not just for small specialist networks trained from scratch. The combination is more powerful than either ingredient alone: the foundation model brings broad physical intuition from pre-training, and the physics-informed objective ensures physical consistency even when labeled data is scarce or entirely absent.
When experimental data is prohibitively expensive or impossible to obtain, purely physics-informed fine-tuning provides supervision with zero observational data — as long as the governing equations are known.
The hybrid strategy takes this a step further. By mixing a small amount of labeled data with physics-based training and a continuous stream of synthetically generated inputs, it achieves the best of both worlds: strong accuracy on familiar inputs, and robust generalization when conditions change. In practical terms, this means a model trained on a handful of examples can still produce physically trustworthy predictions on situations it has never encountered before.
Together, these results point toward a future where AI models for science are not just fast and accurate, but genuinely reliable — tools that respect the laws of nature even when data is hard to come by.
Further reading
- POSEIDON: Efficient Foundation Models for PDEs (Herde et al., NeurIPS 2024)
- Towards a Foundation Model for Partial Differential Equations Across Physics Domains (Soares et al., 2025)
- Physics-Informed Machine Learning (Karniadakis et al., Nature Reviews Physics 2021)
- Physics-informed deep learning for 3D modeling of light diffraction from optical metasurfaces (Medvedev et al., Optics Express 2025)