Tiny Recursive Reinforcement Learning: Can Recursion Speed Up Q-Learning?
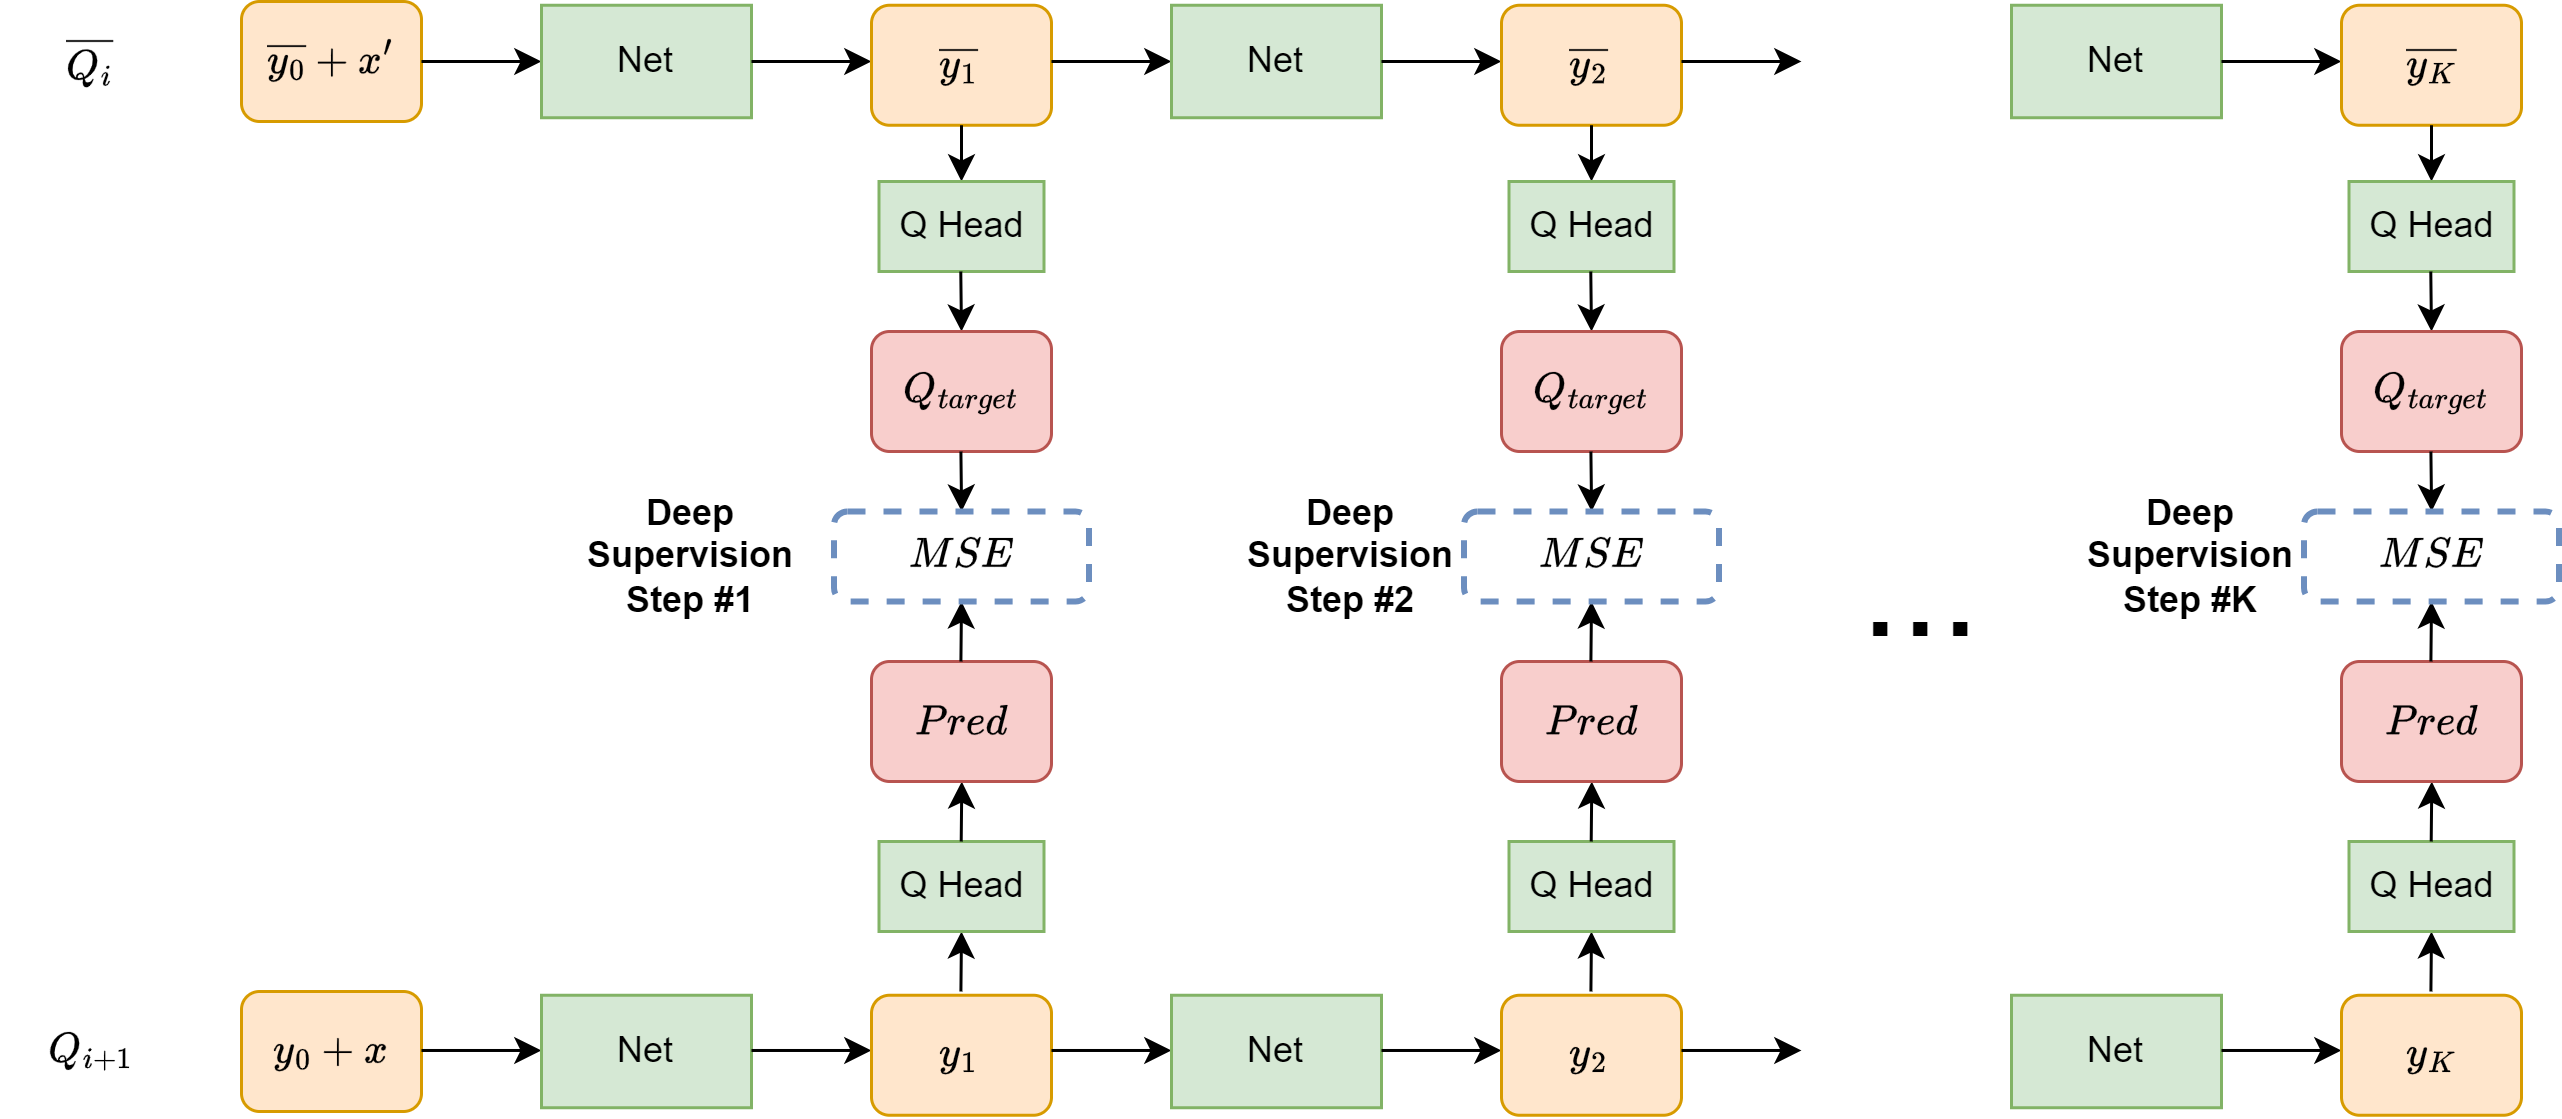
In this blog post we ask a simple question: can the Tiny Recursive Model (TRM), which solves difficult reasoning problems by reusing the same parameters recursively, also be useful for reinforcement learning? We adapted TRM into a Q-network and compared it with standard MLP and CNN architectures. The result was promising, but ultimately mixed: the recursive model sometimes learned faster early in training, but often converged to a worse solution than conventional architectures.
Authors
Rodrigo Coelho